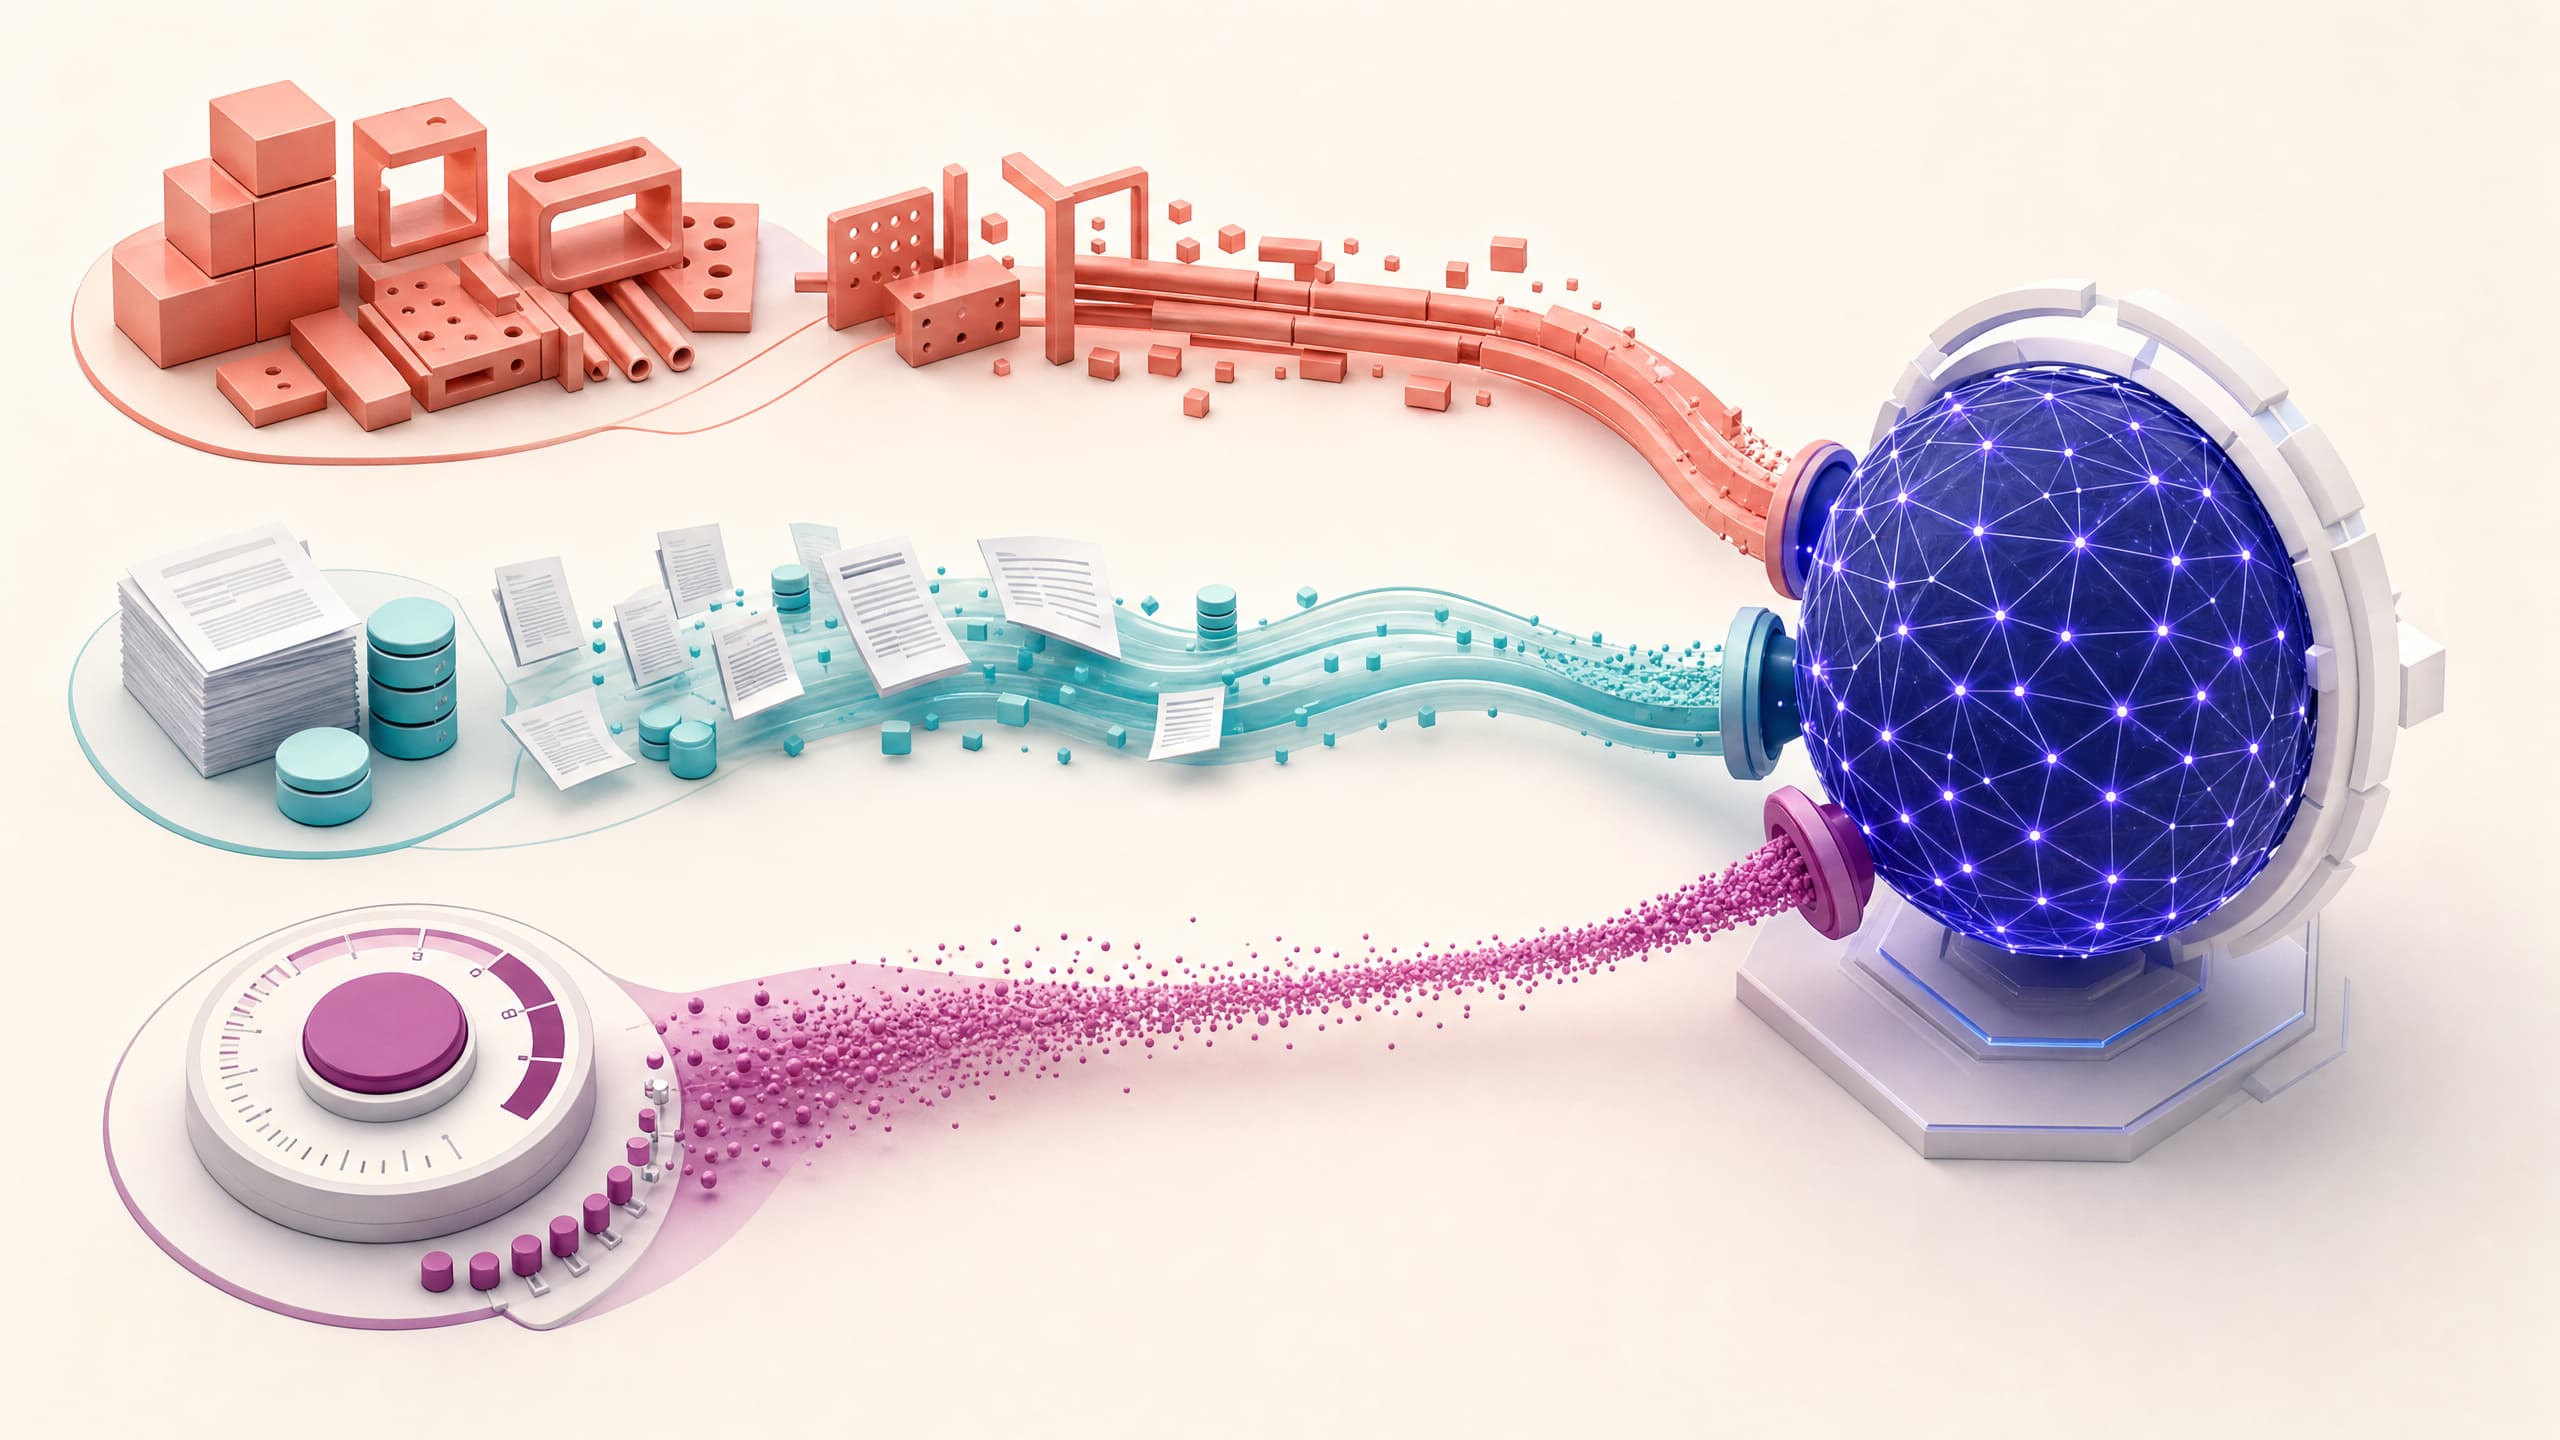
The question that actually determines how an AI product behaves isn't "which model?" It's "where does the work live?" Any useful applied-AI system is a stack of layers, and the model is only one of them. The layers are: the prompt, the context you retrieve, the model's learned weights, and the scaffolding you write around it — tool calls, validation, retry logic, escalation. Every team makes this allocation decision early, most teams make it with their gut, and almost nobody revisits it after the first quarter.
The four places the work can live
- In the prompt. Rarely the answer, always the baseline. If it works with a clean, well-written prompt plus a few examples, start here. This is the only layer that costs you nothing but a text file and can be changed with a deploy.
- In retrieved context. The knowledge that changes — docs, policies, tickets, data — should live in a retrieval layer, not in the model. This is what RAG is for: the model stays generic, the facts stay current, and updating a document updates the product.
- In the weights. Behavioral style — format, tone, domain jargon, the shape of the output the way your business needs it — can be moved into the model with fine-tuning. This is the most expensive layer and the slowest to change. Use it only for the second-order stuff that neither prompts nor context can carry.
- In your scaffolding. Validation, tools, fallbacks, escalation paths, human review gates. This is the only layer you fully control, and it's the one almost every immature team underinvests in. The model you call is replaceable; the machinery around it is your product.
The routing rules
The practical algorithm I use with teams is: push work as far down the stack as possible, with evidence at every step.
Start with the prompt and a golden set of cases. Measure where it fails. If the failures are connected to knowledge — facts, recent information, company-specific detail — the gap is a retrieval problem: add context, fix chunking, improve ranking, and re-measure. If the failures are connected to form — the output doesn't look or behave the way the domain requires — the gap is a style problem, and style is what fine-tuning is actually good at fixing. And if the failures are connected to steps — the task requires doing multiple things in sequence, using tools, reacting to intermediate results — that's a scaffolding problem, and no amount of model work will fix it.
Three rules keep this honest:
- Data availability decides fine-tuning. Fine-tuning is a fiction when the change is a fact ("our pricing page was updated"); it's a claimed capability ("output legal-grade contracts, consistently") and needs a dataset that proves the claim. If you have fifty examples, you have a prompt, not a training set.
- Convexity decides RAG. If the knowledge changes monthly — the product docs, the policy updates, the new pricing — it must live outside the model. The moment you fine-tune facts into weights, every fact change becomes a retraining project with a data pipeline you don't have.
- The error budget decides scaffolding. The question is never "can the model do this?" It's "what happens when it fails, and how cheap is the failure?" Scaffolding is where you spend to make failures cheap: validation, human review, escalation paths. If you can't afford the failure yet, you can't afford to ship the automation.
Why the gut choice is usually the expensive one
The pattern I see most often runs in the opposite direction of the math. A team gets an impressive RAG demo, so they invest in embeddings and chunking for weeks, only to discover their problem was never factual recall — it was that the output format didn't match the system their customers use. Or a founder fine-tunes a model because fine-tuning sounds like "real AI," and then has to retrain it every time the offering changes. The expensive places are chosen first, and the cheap ones are never tried.
The reason the model itself survives every quarter is that it's the cheapest part of the stack to improve — you swap it and re-run your golden set. The layers that compound are the ones you can iterate on without a training job: a sharper prompt, a better retrieval index, validation code that catches the failure mode your golden set found.
The model is a dependency, not a strategy
There's a version of this argument that runs even deeper: the model you picked today is a commodity that will change quarterly, and the architecture that survives is the one where the model is a swappable component behind a contract. Where the work lives is the strategy. Pretending the model is the strategy is just a slower way of paying for the strategy you never designed.
Allocate the work the way you'd allocate a budget: to the layer with the best evidence-to-cost ratio, one experiment at a time, measured against the same golden set. That's not less exciting than contemplating model options. It's just the version that produces a product.